What’s Changed: GLM 4.6 left Venice AI’s chat app in November 2026, and Kimi K2.5 was retired on November 18 according to Venice’s own deprecation tracker. GLM 4.6 never got a tracker entry, and Venice’s public API still lists it. For an ongoing story, GLM 4.7 is the model Venice names as its successor, while DeepSeek V4.1 Flash 1017 Uncensored is the new app default.
Venice AI GLM 4.6 was the model many Venice roleplayers built whole stories around, and in November it dropped out of the chat app’s model menu. Kimi K2.5 went with it, retired on November 18.
Venice’s records do not line up neatly. Its deprecation tracker lists Kimi K2.5 with a removal date, but GLM 4.6 has no entry there, and the public model list for developers still carries it with no retirement flag as of November 20.
I care less about that paperwork than about where your story goes next, so most of this page is the replacement choice.
You get the closest swap, the model with the fewest refusals, Venice’s own roleplay model, and the routes that still reach GLM 4.6 itself.
Did Venice AI Remove GLM 4.6?
Yes, GLM 4.6 left Venice AI’s chat app in November 2026, while Venice’s developer API still lists it.
The app showed a retirement notice first, and the model was gone from menus by November 18.
If you would rather stop managing models altogether, Candy AI is a chat app with its own characters, and its Premium plan lists unlimited text messages.
GLM 4.6 is a large open-weight model from Z.ai, the Chinese lab behind the GLM series. Venice’s own model page lists it at 357 billion total parameters with about 32 billion active per token, and Venice first offered it to Pro users in November 2025.
In the main r/VeniceAI thread, one subscriber describes an in-app message announcing the retirement, and another wrote “It leaves on the 18th of this month apparently.” A third found it gone from the menu before then.
A support reply quoted there sends requests to Venice’s public roadmap and says “If a model ever returns after being removed, it will appear again in the model list.”
My read is that Venice pulled GLM 4.6 from the app’s menu first and left the developer entry alone, though Venice has not said so.
The public model list still shows zai-org-glm-4.6 at $0.43 per million input tokens and $1.75 per million output tokens, with a 198,000-token context and no deprecation notice.
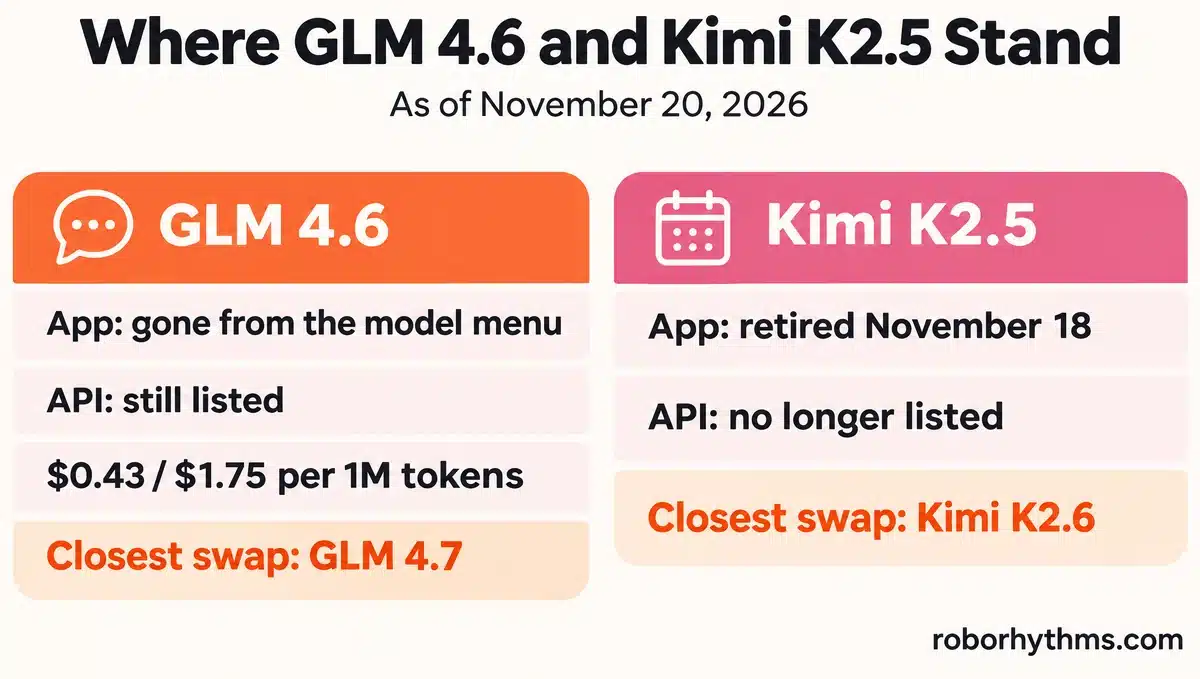
Here is where each retired model stands as of November 20, 2026.
| Model | Venice chat app | Venice API | Closest Venice swap |
|---|---|---|---|
| GLM 4.6 | Gone from the model menu | Still listed, $0.43 / $1.75 per 1M tokens | GLM 4.7 |
| Kimi K2.5 | Retired November 18 | No longer listed | Kimi K2.6 |
When Did Venice Retire Kimi K2.5?
Venice retired Kimi K2.5 on November 18, 2026, the date on its deprecation tracker, and the model no longer appears in its developer model list.
Kimi K2.6 and Kimi K3 from Moonshot AI are still there.
Kimi K2.6 is the closer step, with a 256,000-token context at $0.75 and $3.50 per million tokens on the API. Kimi K3 is a much bigger jump in price, at $3.75 in and $18.75 out per million tokens.
What Should You Use Instead of GLM 4.6 on Venice?
GLM 4.7 is the closest swap, because Venice describes it as “the successor to GLM-4.6,” and DeepSeek V4.1 Flash Uncensored is the pick when refusals are your problem.
Venice’s own roleplay model is a third option, with a short reply cap.
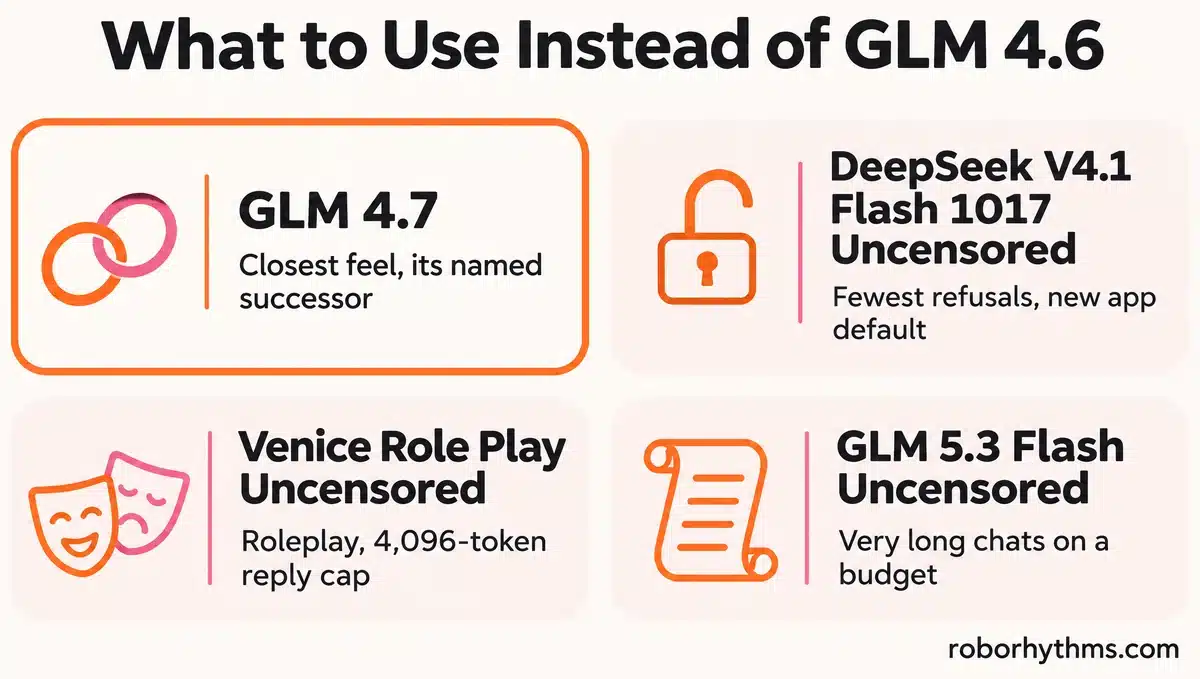
I’d start an ongoing story on GLM 4.7 and keep DeepSeek V4.1 Flash Uncensored for the scenes GLM refuses. That split covers what made GLM 4.6 popular: close prompt-following and a tone that matched the scene.
| Venice model | Best for | Context | API price per 1M tokens (in / out) |
|---|---|---|---|
| GLM 4.7 | Closest feel to GLM 4.6, its named successor | 198,000 | $0.55 / $2.65 |
| DeepSeek V4.1 Flash 1017 Uncensored | Fewest refusals, the app’s new default | 1,000,000 | $0.33 / $1.32 |
| Venice Role Play Uncensored | Roleplay, with replies capped at 4,096 tokens | 128,000 | $0.50 / $2.00 |
| GLM 5.3 Flash Uncensored | Very long chats on a budget | 1,048,576 | $0.165 / $0.55 |
Prices and context sizes come from Venice’s public model list, checked on November 20, 2026.
In the app, Venice Pro costs $18 a month for unlimited text prompts on Pro models, so these per-token prices matter mainly if you use the API or pay in credits.
GLM 4.6 was never flagged as uncensored on Venice. Venice’s own GLM 4.6 page says it was “Not uncensored on Venice: it follows standard safety guidelines,” so the models marked Uncensored above give you more room than GLM 4.6 ever did.
Opinions on the swaps split in the retirement thread, where one regular “tried 4.7 but feel 4.6 is better.” The standard GLM 5.3 draws complaints there about heavy guardrails, and DeepSeek is praised for zero refusals but called too adversarial for roleplay prose.
The newer GLM 5 family is a serious line. TechCrunch reported in August that GLM-5.2 is only a few months behind OpenAI’s GPT-5.5 and Anthropic’s Claude Opus 4.7 on the nonprofit SaferAI’s cyber and bio tests.
Whatever you pick, carry your story over with a short handoff note instead of pasting the whole chat.
Before: “Continue the story from where we left off.”
After: “You are Mara, a dry-humored ship’s medic. Write in past tense, under 250 words per reply, and never speak for my character, Jonah. Last scene: Jonah just found the forged manifest in Mara’s cabin.”
If you are ready to leave Venice entirely, Nectar AI is the other app I point roleplayers to, with ready-made characters and no API setup.
Can You Still Use GLM 4.6 Anywhere?
Yes, GLM 4.6 is still listed on Venice’s developer API and sold by other hosts such as OpenRouter, though none of that puts it back in the Venice chat app.
Each route needs some setup and costs per token.
I wouldn’t build a long project on Venice’s API entry, because a model with no tracker row can disappear with the same short notice.
These are the three routes that still reach GLM 4.6.
- Venice’s API. Create an API key and call the model ID
zai-org-glm-4.6, priced at $0.43 in and $1.75 out per million tokens as of November 20. - OpenRouter. Its public model list sells Z.ai’s GLM 4.6 at $0.50 in and $2.00 out per million tokens, with a 204,800-token context. Kimi K2.5 is there too, at $0.50 in and $2.50 out, and neither shows an end date.
- A chat frontend. Tools like SillyTavern can point at either API, which keeps your characters in one place. Our SillyTavern guide covers the setup, and the best SillyTavern models list compares GLM against the alternatives.
The tradeoff that bothers me is privacy. Venice ran GLM 4.6 under its private, zero-retention tier, and another host’s data policy is its own, so read it before you move a personal story there.
Will Venice Bring GLM 4.6 Back?
Venice has not ruled out a return, but nothing points that way yet.
Venice support directs requests to its public roadmap, and one subscriber who emailed got a free month of Pro but was told the model is “on the path to retirement regardless.”
Emailing has worked before, according to a reply in that thread: “We managed to save the free Deepseek model this way.” If GLM 4.6 does return, Venice says it will reappear in the model list.
Why Does Venice AI Keep Removing Models?
Venice says it retires a model when a newer one does the same job better, when it stops meeting Venice’s reliability bar, or when usage stays low. It now promises 7 to 15 days of notice.
After that date, developer calls route to a similar model at the same or lower price, or fail with a 410 error.
That notice window used to be longer. A Venice moderator’s model lifecycle explainer promised 30 to 60 days of notice about a year ago.
The same moderator told users in the “You didn’t listen” thread that retirements usually come down to low traffic or users moving to newer versions.
GLM 4.6 also had a rough start on Venice. The November 2025 changelog says it was set as the default for all users, “reverted due to high output token volume, and later reapplied.”
I don’t think a 7-day window is fair to someone with months of story on one model, and that is my one real complaint about how Venice handles this.
If you have a model you love there, keep a summary of each long story outside the app so a retirement costs you an evening instead of the plot. Our Venice AI review covers the rest of the platform, from plans to privacy tiers.
Quick Takeaways
- GLM 4.6 left Venice AI’s chat app in November 2026, but Venice’s developer API still listed it on November 20.
- Kimi K2.5 was retired on November 18, and Kimi K2.6 is the closest model still on Venice.
- For an ongoing story, switch to GLM 4.7, and use DeepSeek V4.1 Flash Uncensored for scenes GLM refuses.
- GLM 4.6 is still reachable through Venice’s API or OpenRouter, at about $0.43 to $0.50 per million input tokens.
- Keep a short summary of every long story outside the app, because Venice now gives as little as 7 days of notice.
