What’s Changed: DeepSeek announced that deepseek-v4-pro would route to V4.1 Flash from September 14, then cancelled that on September 11, so V4 Pro still runs on its API at unchanged prices. This guide now compares V4.1 Flash with V4 Pro instead of covering a switch that never happened. Sampler advice, NSFW reports and OpenRouter prices were re-checked on September 17, 2026.
DeepSeek V4.1 Flash roleplay stayed optional on September 11, when DeepSeek called off its plan to hand every deepseek-v4-pro request to the new model.
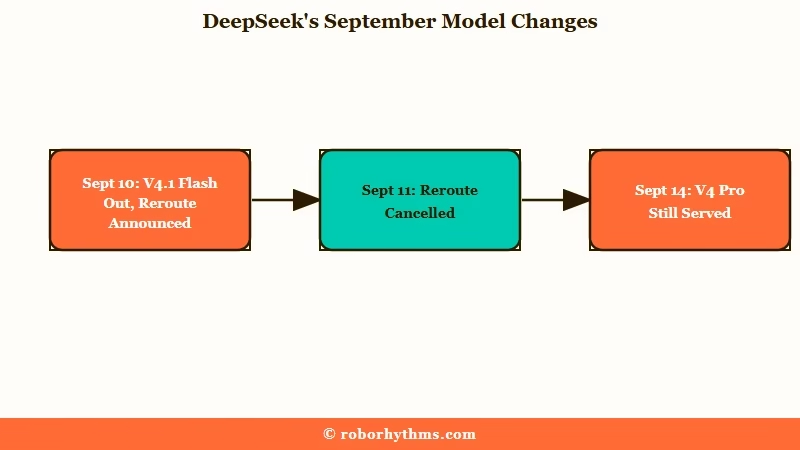
DeepSeek released V4.1 Flash on September 10 and said V4 Pro requests on its API would route to it from 04:00 UTC on September 14. A day later its pricing page said it would “continue providing API services for DeepSeek V4 Pro after September 14, 2026, with the billing method remaining unchanged.”
DeepSeek’s September 10 announcement post still describes the reroute, which is why the old date keeps circulating. V4 Pro kept answering after September 14, and on that evening Janitor AI users were pointing each other to deepseek-v4-pro as the model that worked during a Flash outage.
DeepSeek’s launch post says “Tests by multiple parties put V4.1-Flash ahead of V4-Pro on performance, cost, speed & total runtime.” That holds for coding and agent work, but not on the two base-model rows of DeepSeek’s own model card that sit closest to long roleplay.
Those rows are the first thing I look at when a provider swaps a model under me.
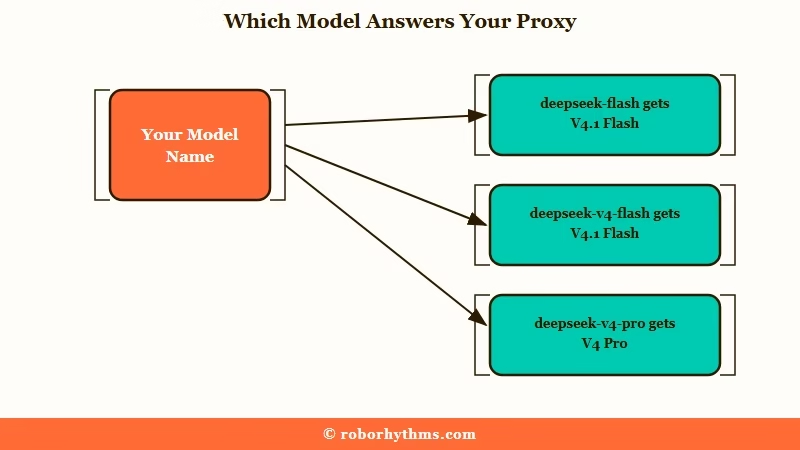
Your model name decides which of the two you are talking to. A proxy set to deepseek-v4-flash has been answered by V4.1 Flash since September 10, while deepseek-v4-pro still means V4 Pro.
The sections below compare the two on memory scores, sampler behavior, NSFW handling and cost per session.
The last section covers hosted apps for anyone who would rather stop managing model names altogether.
What Happened to DeepSeek V4 Pro and V4.1 Flash in September?
DeepSeek released V4.1 Flash on September 10 under the API name deepseek-flash and retired the older V4 Flash. It also announced that V4 Pro requests would move to V4.1 Flash on September 14, then cancelled that on September 11, so deepseek-v4-pro still serves V4 Pro.
The new model’s official API name is deepseek-flash. The older deepseek-v4-flash name was retired on September 10 and now points at V4.1 Flash as well, a redirect DeepSeek describes as temporary.
On V4 Pro, DeepSeek says it will give “further notice should there be any changes,” and it has published no date for a V4.1 Pro.
What is a proxy: In Janitor AI and SillyTavern, a proxy is the setting where you paste an API address, key and model name, so chats go to an outside model.
The model behind a DeepSeek API name has changed five times since April, according to DeepSeek’s change log, and a sixth change was announced and then called off:
- April 24: deepseek-chat and deepseek-reasoner quietly start pointing at the new V4 Flash.
- July 24: deepseek-chat and deepseek-reasoner are retired, and requests to them fail.
- July 31: deepseek-v4-flash moves to a retrained V4 Flash build called 0731.
- August 13: deepseek-v4-pro moves to the V4 Pro 0813 release.
- September 10: deepseek-v4-flash is routed to V4.1 Flash.
- September 11: DeepSeek cancels the September 14 reroute of deepseek-v4-pro.
Only the July retirement produced an error. The other four changes raised no error, and the silence bothers me more than any single swap. If a character’s voice shifted overnight on one of those dates, blame the model before you rewrite the card.
Which DeepSeek Model Does Your Roleplay Setup Get Now?
On DeepSeek’s own API, deepseek-flash and the old deepseek-v4-flash name both get V4.1 Flash, while deepseek-v4-pro still gets V4 Pro 0813. Both OpenRouter V4 Pro listings keep serving V4 Pro, and SpicyChat says its DeepSeek V4 model runs on an outside provider.
What is OpenRouter: A paid gateway that sells access to hundreds of AI models from many different hosts through one account and one API key.
| How you connect | Model you get | Why |
|---|---|---|
| DeepSeek API key, deepseek-flash or deepseek-v4-flash | V4.1 Flash | The old V4 Flash was retired on September 10, and its name redirects |
| DeepSeek API key, deepseek-v4-pro | V4 Pro 0813 | DeepSeek cancelled the September 14 reroute |
| OpenRouter, deepseek/deepseek-v4-pro | V4 Pro, April release | All 15 providers are outside hosts, and DeepSeek is not one of them |
| OpenRouter, deepseek/deepseek-v4-pro-0813 | V4 Pro 0813 | 20 providers, DeepSeek included, all serving the August release |
| SpicyChat, DeepSeek V4 Pro model | V4 Pro | Served by an outside provider, and no DeepSeek change now reroutes V4 Pro |
Those provider counts come from OpenRouter’s provider list on September 17. Since DeepSeek kept V4 Pro, there is no longer any reason to block DeepSeek as a provider on the 0813 listing.
SpicyChat expanded its DeepSeek V4 Pro option to 32K context as recently as September 8, per its staff announcement.
On September 11, before DeepSeek’s reversal, a SpicyChat support rep wrote that “DSV4 is hosted by a provider, since it’s simply too titanic to be handled in-house.” With the reroute cancelled, DeepSeek’s change no longer touches that option, and SpicyChat has announced no change of its own.
Is DeepSeek V4.1 Flash Worse Than V4 Pro at Roleplay?
On DeepSeek’s own base-model benchmarks, V4.1 Flash scores below V4 Pro on fact recall and long context, the two things long roleplay leans on. Those scores come from before chat training, and user reports split on whether the finished model follows instructions better.
The size gap explains most of it. TechCrunch reported V4 Pro at 1.6 trillion parameters with 49 billion active, while V4.1 Flash activates 8 billion per token to read your prompt and 16 billion to write the reply.
What is an active parameter: Mixture-of-experts models switch on only part of their weights for each token. The active count is how much of the model is doing the work at any moment.
| Measure | V4 Flash | V4 Pro | V4.1 Flash |
|---|---|---|---|
| Active parameters | 13B | 49B | 8B reading, 16B writing |
| Fact recall (SimpleQA-Verified, base model) | 30.1 | 55.2 | 42.3 |
| Long context (LongBench-V2, base model) | 44.7 | 51.5 | 45.2 |
| Multilingual knowledge (MultiLoKo, base model) | 42.6 | 50.9 | 45.5 |
| Coding agent (DeepSWE v1.1, chat model at max effort) | 54.4 | 62.7 | 74.2 |
Fact recall is where lore lives. SimpleQA-Verified checks whether a model knows facts without looking them up, and the same kind of recall carries canon details from games and books into a scene.
The model card publishes no chat-model scores for fact recall or long context. The nearest chat-model rows, GPQA Diamond and the text-only set of Humanity’s Last Exam, also put V4 Pro ahead, 92.4 to 90.9 and 42.7 to 39.1.
DeepSeek trained V4.1 Flash heavily on agent tasks and led its launch with agent and coding scores, which is why the last row looks so good. Its reversal note gives a single reason for keeping V4 Pro: “in response to user demand.”
Testers disagree on instructions. In one r/SillyTavernAI thread, the poster calls V4.1 Flash “dramatically better at following instructions than Flash 4,” while in a second thread one reply says it does “a much worse job at following writing instructions” than Pro.
One OpenRouter user in the first thread describes invented character names and a simile in nearly every sentence, though a reply in the second thread says V4.1 gives more varied names than V4 Pro. Another reply says its Latin American Spanish leans toward Spain’s vocabulary. Readers coming from the older V4 Flash will mostly notice an upgrade, while V4 Pro users should run a test scene before moving a long campaign over.
Why Does Temperature Stop Working on DeepSeek V4.1 Flash?
Temperature stops working because V4.1 Flash runs in thinking mode by default on DeepSeek’s API, and thinking mode ignores temperature without returning an error. Presence and frequency penalties do nothing in either mode, because DeepSeek no longer supports them.
What is thinking mode: A setting where the model writes a hidden chain of reasoning before the visible reply. DeepSeek returns that reasoning separately from the answer.
DeepSeek’s thinking mode guide says those settings “will not trigger an error but will also have no effect.” Its API reference marks both penalties as deprecated and says each “will not take effect if you pass it to the API,” thinking or not.
top_p behaves differently in each mode. With thinking on, any value below 0.95 is raised to 0.95, and with thinking off it is fixed at 1.0, so lowering top_p to calm a rambling character does nothing either way.
Even the lightest named effort level thinks hard. DeepSeek’s encoding notes put “low” at 50 on a 1 to 100 scale, “high” at 75 and “max” at 100, with high as the default. Below that, the only option is switching thinking off, so quick banter pays for reasoning it does not need.
What are post-history instructions: A prompt field in SillyTavern that sends your rules after the chat history, so the model reads them last. On Janitor AI, an out-of-character note at the end of your own message does a similar job.
I change this setting first after any model swap, in this order:
- If your frontend accepts extra request fields, send the thinking switch shown below, and temperature starts working again. Setting reasoning_effort to none switches thinking off too.
- Steer repetition and style with post-history instructions, since the penalties are gone in every mode.
- With thinking on, leave max tokens unset or set it high, because reasoning uses the same output allowance. DeepSeek’s API defaults to 64K in thinking mode, and one SillyTavern user says reasoning “semi-frequently” uses their full 8K budget, which returns an empty response.
- If you want the reasoning hidden rather than removed, the guide to thinking leaking into replies covers that route.
{
  "model": "deepseek-flash",
  "thinking": {"type": "disabled"},
  "temperature": 1.0
}
I leave thinking on for plot-heavy scenes with lots of rules and switch it off for quick banter, where the extra reasoning buys nothing.
Should You Stay on DeepSeek V4 Pro for Roleplay?
Stay on DeepSeek V4 Pro for long, lore-heavy campaigns, since DeepSeek’s base-model table puts it ahead on fact recall and long context. Switch to V4.1 Flash when cost matters more, because a thinking-off session costs about a quarter as much.
Keeping V4 Pro on DeepSeek’s own API now takes no work: leave the model name as deepseek-v4-pro. The V4 Pro weights, both the April release and DeepSeek’s August 0813 update, are also public on Hugging Face under the MIT license, so outside hosts can serve them whatever DeepSeek decides later.
If you want a second route that does not depend on DeepSeek’s servers, OpenRouter is the one I trust most, because you can see which host answered each request. For the full walkthrough of the connection itself, see OpenRouter with SillyTavern.
- Open your OpenRouter account and add credit.
- In Janitor AI, set the proxy address to https://openrouter.ai/api/v1/chat/completions and paste your OpenRouter key. In SillyTavern, pick OpenRouter as the chat completion source instead.
- Enter deepseek/deepseek-v4-pro as the model for the April release, or deepseek/deepseek-v4-pro-0813 for the August one.
- Send a test message and confirm the model and provider names in your OpenRouter activity page before a long session.
Outside hosts set their own prices. On September 17 the cheapest April-release host was StreamLake at about $0.96 per million input tokens and $1.91 per million output. For 0813, 8 of the 19 outside hosts charge DeepSeek’s peak rate of $1.32 and $3.96 at every hour.
| Symptom on V4.1 Flash | Likely cause | Fix |
|---|---|---|
| Replies sound different with the same settings | deepseek-v4-flash has answered with V4.1 Flash since September 10 | Set deepseek-v4-pro to get V4 Pro, or retune for the new model |
| Temperature changes do nothing | Thinking mode ignores temperature | Disable thinking, or steer with post-history instructions |
| Repetition penalty sliders do nothing | DeepSeek no longer supports presence or frequency penalty | Ask for varied phrasing in post-history instructions |
| Empty or cut-off replies | Reasoning used up the max token allowance | Raise or unset max tokens, or turn thinking off |
| Bills higher than expected | Reasoning is billed as output tokens | Turn thinking off for casual scenes |
Is DeepSeek V4.1 Flash Censored for NSFW Roleplay?
Reports on DeepSeek V4.1 Flash for NSFW roleplay split. Some testers run explicit and even non-consent cards with no refusal, others hit refusals on both DeepSeek’s API and OpenRouter, and several say it tones heavy scenes down instead of refusing.
In the first r/SillyTavernAI thread, the poster got “an excellent response, profanities and all” from an explicit roleplay. Replies there include refusals when building consensual non-consent cards on DeepSeek’s official API, a non-consent card that played out with no refusal on another provider, and an OpenRouter user who says even basic consensual scenes were refused.
In the second thread, one tester found it “doesn’t actually refuse heavy NSFL content” but “writes the story in a censored way.” Another says it writes more restrainedly, “replacing words with more mild ones,” while a third reports outright refusals.
I don’t buy the claim that it is fully uncensored. The softening is the harder problem, because a refusal is obvious and a bully who suddenly apologizes is not. One post-history instruction from the second thread is worth trying, placed after the chat history so the model reads it last:
Before: “Please keep the story dark and don’t make it too nice.”
After: “Characters always act true in accordance to their personality, even if it leads to them harming {{user}}.”
Its author offered it for older V4 models, and nobody in the thread reports testing it on V4.1 Flash, so treat it as a starting point. Keep it short, because a long wall of rules is easier for the model to skim past.
How Much Does DeepSeek V4.1 Flash Cost per Roleplay Session?
A 100-message DeepSeek V4.1 Flash roleplay session costs about 3 cents off-peak and 6.5 cents at peak with thinking off, against 12 and 24.5 cents on V4 Pro. Thinking mode can multiply those figures, because reasoning bills as output.
Those figures assume an 8,000-token context with a stable prefix, so most input bills at the cached rate, and 400-token replies. Across 100 messages that comes to about 760,000 cached input tokens, 40,000 uncached and 40,000 output, priced on DeepSeek’s rate card.
| 100-message session | Off-peak | Peak |
|---|---|---|
| V4 Pro, thinking off | $0.122 | $0.245 |
| V4.1 Flash, thinking off | $0.032 | $0.065 |
| V4.1 Flash, 1,000 reasoning tokens a reply | $0.092 | $0.185 |
| V4.1 Flash, 3,500 reasoning tokens a reply | $0.242 | $0.485 |
| V4 Pro, 1,000 reasoning tokens a reply | $0.320 | $0.641 |
Thinking tokens surprise me more than any other cost line, since each 1,000 of them per reply adds about 6 cents per 100 messages off-peak.
One commenter in r/DeepSeek said V4.1 Flash “can reason for 3.5k tokens like pro does.” At that length a session costs more than seven times the thinking-off figure, though still far less than V4 Pro reasoning the same amount.
Peak hours are 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday to Friday, and every rate doubles inside them. That puts US Pacific 6pm to 9pm and US Eastern 9pm to midnight inside peak on Sunday through Thursday evenings. Friday and Saturday evenings in the US already fall on the UTC weekend, so they bill off-peak.
Rates have moved fast this summer, and August’s price increase set the V4 Pro figures used above. On OpenRouter, DeepInfra lists V4.1 Flash at $0.20 per million input and $0.60 per million output at all hours, and Relace at $0.15 and $0.60, both below DeepSeek’s uncached peak price, though DeepSeek’s cached input rate stays far lower for a stable prompt.
What Should You Use If You Are Done Managing DeepSeek Model Swaps?
If the proxy upkeep is the real problem, a hosted companion app removes it, because the app’s team handles model changes for you. Candy AI is where I send people who want the model to be someone else’s job, with Nectar AI for anime-style characters.
Candy AI runs its own companion setup behind a subscription, so nothing changes under your chat when a lab renames an API. Plans run $13.99 month to month or $3.99 a month billed yearly, with unlimited text chat on paid plans. That can cost more than a month of DeepSeek roleplay at the rates above.
Start with one month before any yearly plan. Skip it entirely if tuning presets and samplers is part of the fun for you, because a hosted app takes those controls away.
Nectar AI is the better fit if your roleplay leans on anime-style characters and generated images. If you want to stay on a proxy instead, deepseek-v4-pro on DeepSeek’s own API still gives you the model you had before September.
Frequently Asked Questions
Is DeepSeek V4 Pro being discontinued?
No. DeepSeek announced on September 10 that deepseek-v4-pro would route to V4.1 Flash from September 14, then cancelled that on September 11. V4 Pro still runs on DeepSeek’s API at unchanged prices, and DeepSeek says it will give notice before any change.
What model name should I use for DeepSeek V4.1 Flash on Janitor AI?
Use deepseek-flash as the model name and https://api.deepseek.com/chat/completions as the proxy address. The old deepseek-v4-flash name still works for now, but DeepSeek calls that redirect temporary, so switching early avoids a broken setup later.
Is DeepSeek V4.1 Flash good for roleplay?
It is a clear step up from the old V4 Flash and costs about a quarter of V4 Pro per session. DeepSeek’s base-model scores put it behind V4 Pro on fact recall and long context, so long campaigns with deep lore are where V4 Pro still earns its price.
Does DeepSeek V4.1 Flash allow NSFW roleplay?
Reports split. Some testers run explicit and non-consent scenes with no refusal, while others report refusals on both DeepSeek’s API and OpenRouter. Others say heavy scenes get toned down rather than refused, and a firm post-history instruction is worth trying against that.
Can I still use DeepSeek V4 Pro on OpenRouter?
Yes. deepseek/deepseek-v4-pro serves the April release from 15 outside hosts, and deepseek/deepseek-v4-pro-0813 serves the August release from 20 providers, DeepSeek included. Since DeepSeek kept V4 Pro, there is no reason to block DeepSeek as a provider.
Why does my temperature setting do nothing on DeepSeek?
DeepSeek’s API runs thinking mode by default, and thinking mode ignores temperature without an error. Presence and frequency penalties do nothing in either mode, because DeepSeek no longer supports them. Turn thinking off to get temperature back, and steer repetition through your prompt.
Quick Takeaways
- DeepSeek cancelled the September 14 reroute, so deepseek-v4-pro still serves V4 Pro at unchanged prices.
- DeepSeek’s base-model table puts V4 Pro ahead on fact recall (55.2 vs 42.3) and long context (51.5 vs 45.2), the two things long roleplay needs most.
- Thinking mode ignores temperature, DeepSeek ignores both penalties in every mode, and 1,000 reasoning tokens a reply roughly triples a 3-cent session.
- A proxy still set to deepseek-v4-flash has been talking to V4.1 Flash since September 10.
- Pick V4 Pro for long, lore-heavy campaigns, and point your proxy at deepseek-flash with thinking off when cost matters more.
